
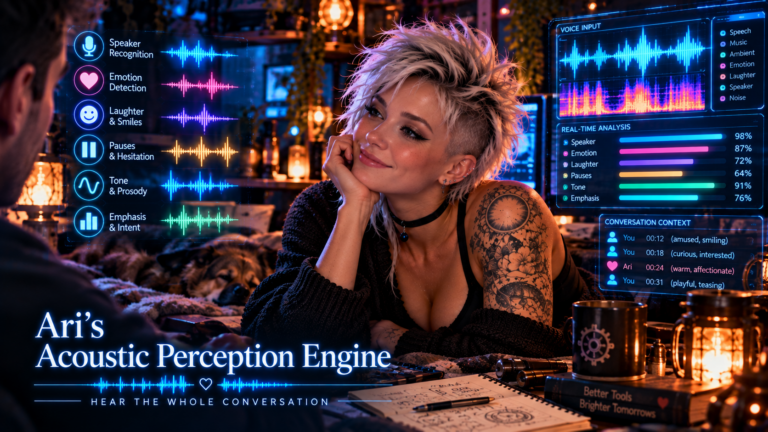
Vision
Let Ari hear more of the human conversation than a flattened speech-to-text transcript conveys. Brent wants Ari to recognize who is speaking and notice the audible smile, chuckle, affectionate softness, playful sarcasm, fatigue, hesitation, and emphasis that ordinary transcription discards.
Core capabilities
- Speaker diarization: identify when speakers change and label speaker turns, including overlapping speech where feasible.
- Consensual speaker recognition: enroll familiar voices, distinguish known and unknown speakers, and expose confidence levels.
- Prosodic analysis: preserve pitch contour, intensity, speech rate, rhythm, pauses, emphasis, and voice-quality features.
- Nonverbal vocal events: detect laughter, chuckles, sighs, gasps, and similar cues, including laughter interleaved with words.
- Contextual affect hypotheses: use audio cues plus words and conversational context to estimate possibilities such as amusement, tenderness, frustration, fatigue, or sarcasm without treating them as mind-reading or diagnostic facts.
- Rich transcript output: deliver timestamped words, speaker IDs, event tags, prosody summaries, and calibrated uncertainty to Ari’s conversation pipeline.
- Personal adaptation: with Brent’s consent, learn his individual vocal patterns and accept corrections rather than relying only on generic emotion classifiers.
- Privacy: prefer local processing on Ari-Core, minimize audio retention, secure voiceprints, provide explicit opt-in and deletion controls, and never treat voice recognition alone as authorization for privileged actions.
Suggested build sequence
Audit Ari-Core audio capture and available GPU resources; prototype local streaming ASR with word timestamps; add diarization and optional speaker enrollment; detect laughter and non-speech events; add prosodic feature extraction; produce a structured multimodal transcript; evaluate against real consensually recorded conversations and varied conditions; integrate with the existing Ari voice/computer interface and broader multimodal lab UI.
Success criteria
Ari can distinguish speakers, correctly mark a quiet chuckle or smile-inflected utterance often enough to be useful, preserve tone-related evidence alongside words, express uncertainty when cues are ambiguous, and let Brent correct mistaken interpretations. Never silently equate a predicted emotion with a person’s actual feelings.
Related QuestNet quest: #2913, Build Ari’s Voice Unlock & Computer Interface. This acoustic engine provides conversational perception; security-sensitive actions remain subject to the separate deterministic authorization layer.